


For years, “Google runs JavaScript” has been the line that closes the client-side rendering SEO debate. It’s true for Google. It doesn’t hold for the AI crawlers and coding agents now reading your documentation, and when it fails, it fails silently.
Why teams believe client-side rendering is fine for SEO
Google’s JavaScript SEO basics describes three phases: crawling, rendering and indexing. In the rendering phase, “a headless Chromium renders the page and executes” the JavaScript. Teams read that as a general rule and built docs sites as single-page apps.
The same page carries a caveat most people skimmed: “server-side or pre-rendering is still a great idea because it makes your website faster for users and crawlers, and not all bots can run JavaScript.” That last clause is the whole story of this post.
AI crawlers and agents don’t run your JavaScript
Vercel looked at AI crawler traffic across its network in The rise of the AI crawler (December 2024) and found that “none of the major AI crawlers currently render JavaScript”, covering OpenAI, Anthropic, Meta, ByteDance and Perplexity. ChatGPT’s crawler did fetch JavaScript files (11.50% of its requests) and so did Claude’s (23.84%), but neither executed them. Gemini and AppleBot were the exceptions: Gemini uses Googlebot’s infrastructure, and AppleBot renders through a browser-based crawler.
These are not fringe clients. In the same analysis, GPTBot made 569 million fetches and Claude 370 million across Vercel’s network in a month, against 4.5 billion for Googlebot.
Crawlers are one thing. The coding agents your customers use day to day matter more, and most of them behave the same way. The draft Agent-Friendly Documentation Spec states that “most coding agents fetch pages using HTTP libraries that do not execute JavaScript”, and that “GitHub Copilot is the only major agent observed to use headless browser rendering.” Both sources describe behaviour at the time they were written, not permanent properties, but that is what your docs face today.
What the agent actually receives
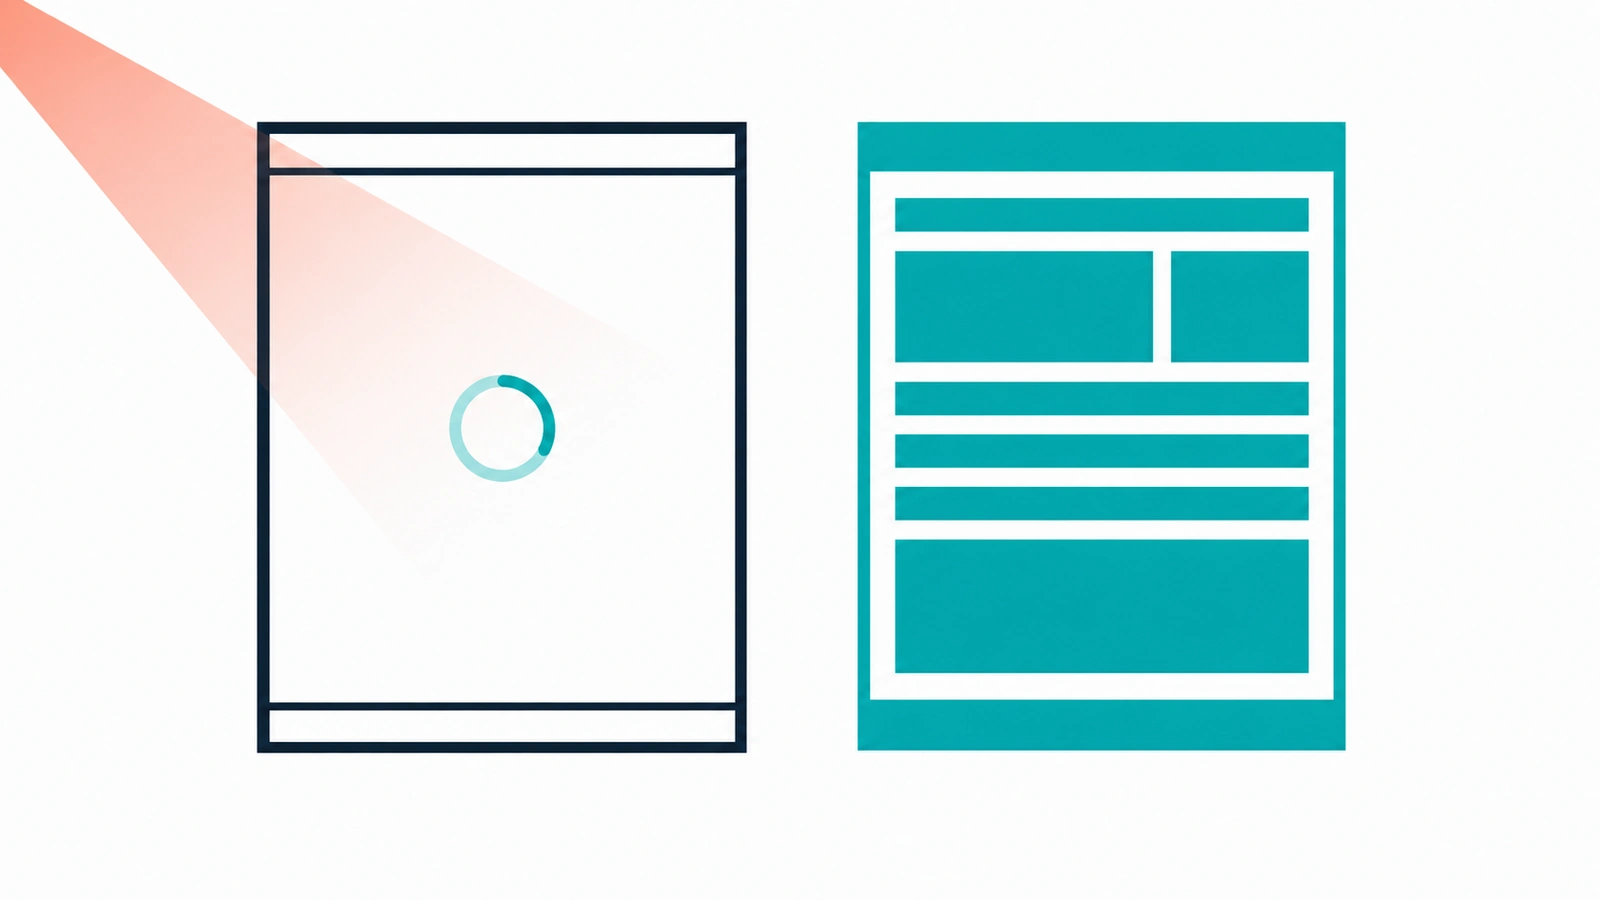
Picture a client-rendered docs page as raw HTML. The body holds a single empty mount point, a few script tags and perhaps some inline styles. The spec’s rendering-strategy check describes what agents see as “an empty shell containing framework boilerplate, inline CSS, and navigation chrome, but none of the documentation content.”
A person loading that page sees a spinner for half a second, then the docs. The agent doesn’t wait, and has no reason to. The spec calls this “a zero-content problem”: the page “returns HTTP 200, so the agent doesn’t know anything is wrong.” It tries to extract an answer from the nav links and footer, or falls back on training data that may be outdated. The developer sees a confident answer and never learns your docs were skipped.
That silence is the real cost. A broken page in a browser gets reported. An empty page fetched by an agent produces plausible code against an old version of your API, and the bug report blames your product.
One nuance worth knowing: “we use Next.js” doesn’t tell you which side you’re on. Server-rendered and client-rendered sites share the same markers (id="__next", id="___gatsby", id="__nuxt"), and the spec notes that “framework markers alone are not conclusive since SSR sites share the same markers.” It makes the point directly: rendering strategy “is a property of the framework configuration, not the framework itself.” Only the response body tells you what an agent gets.
Server-side rendering vs static generation, in one minute
The definitions from web.dev’s Rendering on the Web:
- Server-side rendering (SSR): rendering on the server “to send HTML, rather than JavaScript, to the client”.
- Static rendering: happens at build time and produces “a separate HTML file for each URL ahead of time”.
- Client-side rendering (CSR): rendering in the browser, “using JavaScript to modify the DOM”.
- Hydration: running client-side scripts “to add application state and interactivity to server-rendered HTML”.
For documentation, static generation is usually the natural fit in our view: content changes when you deploy, not per request, so you can build the HTML once and serve it from anywhere. SSR works too, at the cost of running a server. Either way, agents get text.
The fix is usually configuration
Most teams don’t need a rewrite.
Docusaurus already does the right thing. Its static site generation docs explain that at build time “SSR produces static HTML pages”, and React then hydrates that markup in the browser. If a Docusaurus site fails the check, look at custom components that load their content in the browser.
Next.js can emit static HTML with output: 'export'. The static exports guide says that “when running next build, Next.js generates an HTML file per route”. The catch is client components that fetch data in the browser: the guide’s own example returns 'Loading...' until data arrives, so that placeholder, not your content, is what lands in the prerendered HTML. On docs sites, check API reference widgets, tabbed code samples and versioned content loaded on the client. The spec flags the same pattern: a statically generated page where one component defers its content to JavaScript looks, to an agent, the same as a full SPA shell.
The rule we work to: page content comes from the build or the server. Interactivity (search, copy buttons, try-it consoles) can stay client-side.
How to check it
Pick a sentence from the body of a real docs page (not the title, which may also appear in a meta tag) and look for it in the raw HTML:
curl -s https://docs.example.com/guides/authentication | grep -c "rotate your API key"0 means the text is built by JavaScript after load, and agents won’t see it. Then compare the size of the raw response with what the browser shows:
curl -s https://docs.example.com/guides/authentication | sed 's/<[^>]*>//g' | wc -wA few dozen words for a long page is a shell. The spec’s companion CLI, afdocs, automates this as its rendering-strategy check. The curl test is also cheap enough to run in CI against a handful of key pages; see five CI workflows for documentation.
Rendering comes first
Rendering is a precondition for everything else in agent readiness. An llms.txt file points agents at your pages, but if those pages are empty shells, the index leads nowhere. The same applies with more force to API reference, which is often the most client-heavy part of a docs site; we cover that in agent-ready API docs. For the wider argument, see writing docs for humans and AI agents.
Get the full checklist
Server-rendered is one of the 16 checks in our agent-ready docs checklist. It sits in the Read layer and is rated Critical. Get the free checklist.
References
- Google Search Central, JavaScript SEO basics
- Vercel, The rise of the AI crawler (December 2024)
- Agent-Friendly Documentation Spec (SPEC.md), rendering-strategy check
- web.dev, Rendering on the Web
- Docusaurus docs, Static site generation
- Next.js docs, Static exports
- Agent-Friendly Documentation Spec README